Record the pattern
We establish when the issue appears, who it affects and what changed.
A practical way forward
Repeated fixes are expensive because the team loses time every time the problem returns. We gather evidence, find the dependency behind the symptom and fix the cause in a controlled way.
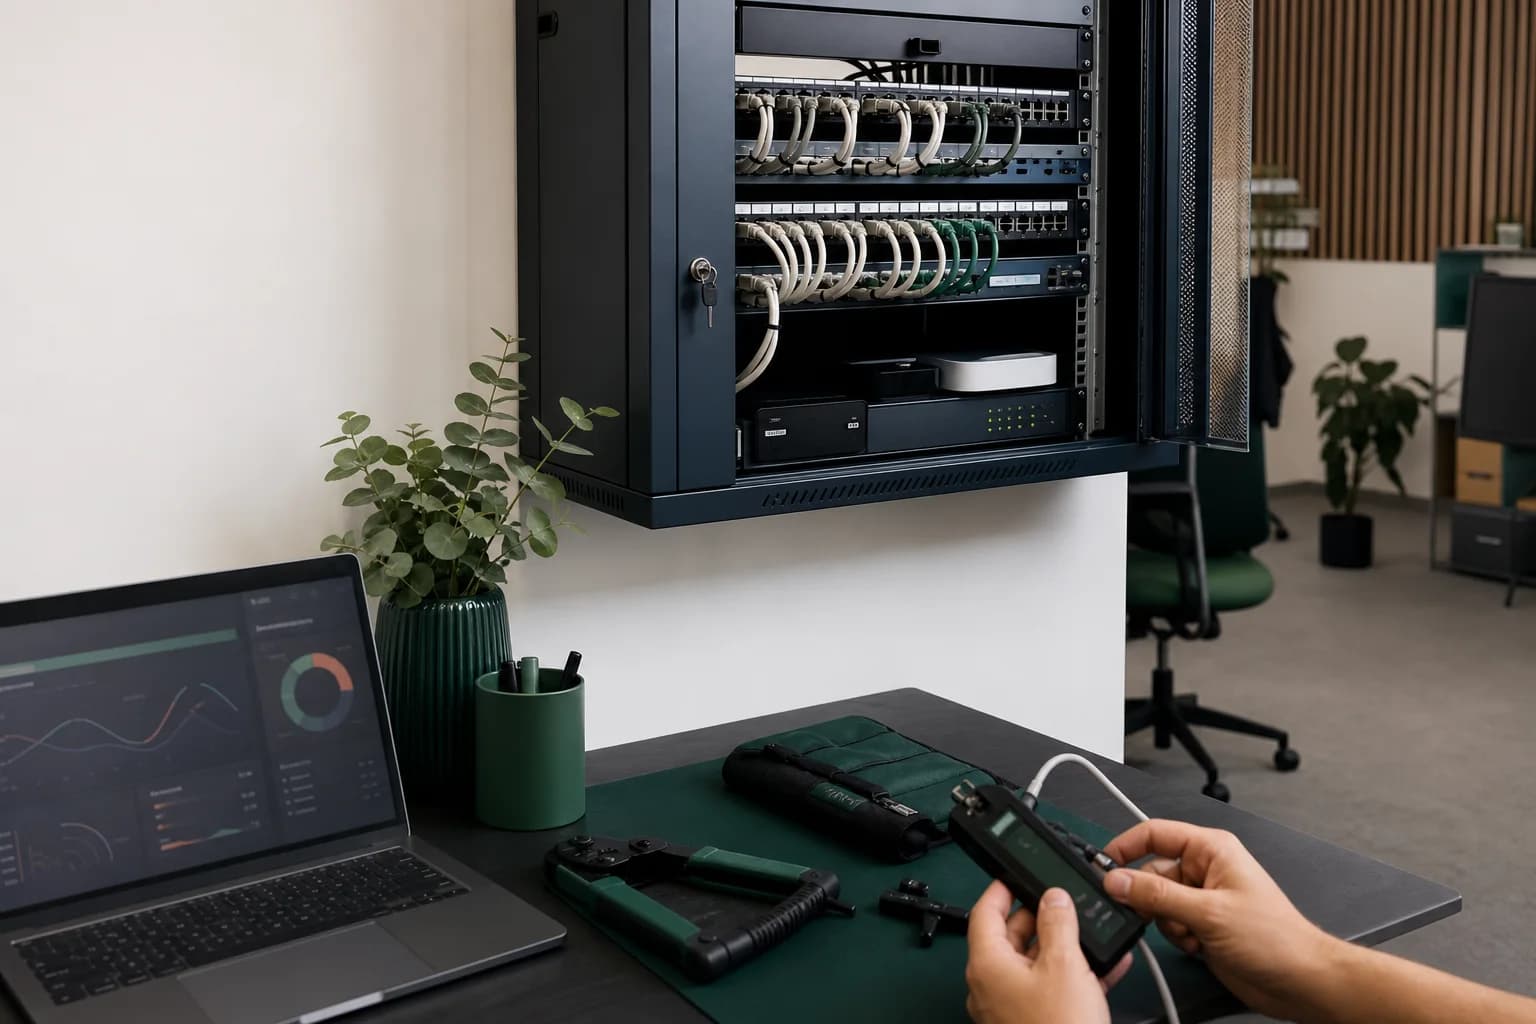
We establish when the issue appears, who it affects and what changed.
We check capacity, events, traffic and dependencies instead of guessing.
We plan changes by impact and verify the result after implementation.
We document the work and add useful monitoring where it helps.
The final scope follows your current systems and the work you want us to own.
Usually not. We recommend replacement only when measurements show that equipment, support status or capacity is part of the problem.
Yes, but intermittent faults need enough monitoring and context to capture the event. We agree what evidence to collect first.
Free initial technical audit
We check the systems, access, backups and recurring problems that matter most. You receive a short, prioritised report with what is sound, what needs attention and what can wait. You decide what happens after that.